Attention Is All You Need
Table of Contents
1. Transformer Architecture Research Notes
1.1. Overview
The Transformer architecture, introduced in "Attention Is All You Need" (Vaswani et al., 2017), revolutionized natural language processing by eliminating recurrence and introducing self-attention.
1.2. Architecture Visualization
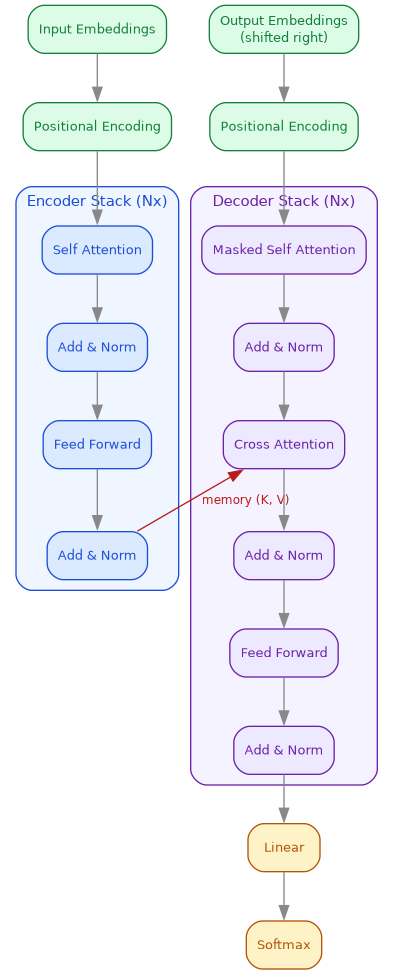
Both stacks take embeddings summed with a positional encoding. The encoder's
final Add & Norm is the memory that cross attention reads in the decoder; the
decoder's final Add & Norm goes through a linear projection and a
softmax over the vocabulary.
1.3. Multi-Head Attention Detail
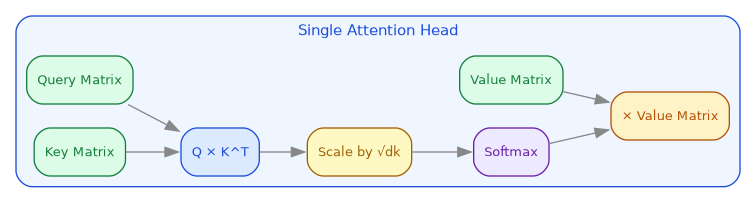
One head of scaled dot-product attention. Each of the eight heads runs this
on its own projection of Q, K, and V; the results are concatenated and
projected once more by W_o.
1.4. Implementation
1.4.1. Multi-Head Attention
    import torch
    import torch.nn as nn
    from typing import Optional, Tuple
    import math

    class MultiHeadAttention(nn.Module):
        def __init__(self, d_model: int, num_heads: int, dropout: float = 0.1):
            super().__init__()
            assert d_model % num_heads == 0, "d_model must be divisible by num_heads"

            self.d_model: int = d_model
            self.num_heads: int = num_heads
            self.d_k: int = d_model // num_heads

            # Linear projections
            self.W_q = nn.Linear(d_model, d_model)
            self.W_k = nn.Linear(d_model, d_model)
            self.W_v = nn.Linear(d_model, d_model)
            self.W_o = nn.Linear(d_model, d_model)

            self.dropout = nn.Dropout(dropout)
1.4.2. Positional Encoding
    class PositionalEncoding(nn.Module):
        def __init__(self, d_model: int, max_seq_length: int = 5000):
            super().__init__()

            pe = torch.zeros(max_seq_length, d_model)
            position = torch.arange(0, max_seq_length, dtype=torch.float).unsqueeze(1)
            div_term = torch.exp(
                torch.arange(0, d_model, 2).float() * (-math.log(10000.0) / d_model)
            )

            pe[:, 0::2] = torch.sin(position * div_term)
            pe[:, 1::2] = torch.cos(position * div_term)
            pe = pe.unsqueeze(0)

            self.register_buffer('pe', pe)
1.5. Key Parameters
| Parameter | Value | Description |
|---|---|---|
| d_model | 512 | Model dimension |
| num_heads | 8 | Number of attention heads |
| d_ff | 2048 | Feed-forward network dimension |
| num_layers | 6 | Number of encoder/decoder layers |
| dropout | 0.1 | Dropout rate |
1.6. References
- Vaswani, A., et al. (2017). Attention Is All You Need. In Advances in Neural Information Processing Systems.
- The Annotated Transformer - Harvard NLP
- PyTorch Documentation - nn.MultiheadAttention
1.7. TODO Implementation Tasks [0/3]
[ ]Add layer normalization implementation[ ]Implement full encoder block[ ]Add training loop with example data
1.8. Notes
- The architecture eliminates the need for recurrence and convolutions
- Attention weights provide interpretability
- Positional encoding enables sequence awareness
- Parallel processing enables efficient training
2. Related
- Formal Verification of Transformer Architectures in Rocq – the same architecture with its dimensions checked by types
- Qwen3.6 and the KV Cache Constraint – what attention costs at inference
- Neural Network Activation Functions – the
softmaxinside each head